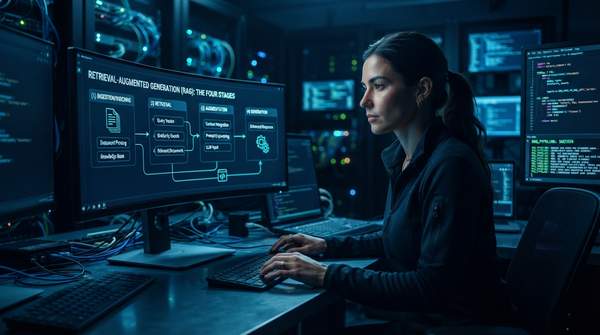
Retrieval-augmented generation, or RAG, is an architecture that connects a large language model to external knowledge bases so it can produce more accurate, current, and domain-specific responses. Instead of relying solely on static training data, a RAG system retrieves relevant documents at query time and feeds them into the model as context, a definition offered consistently by Databricks, IBM, and a widely cited arXiv survey of the field. The architecture works as a sequence of four functional stages—indexing, retrieval, augmentation, and generation—and its effectiveness is measured through retrieval relevance and response groundedness rather than conventional LLM benchmarks alone.
Understanding Retrieval-Augmented Generation (RAG)
Generative AI models are trained on large datasets and refer to that information when generating outputs, as IBM's explainer puts it. That training corpus is fixed: it cannot incorporate facts that postdate training, and it may not contain an organization's proprietary manuals, policies, or research. RAG addresses both gaps by connecting the model with supplemental external data at query time. The arXiv survey "Retrieval-Augmented Generation for Large Language Models," which systematically examines the field's retrieval, generation, and augmentation components, treats this tripartite structure as the foundation of every RAG framework.
The practical payoff is twofold. First, grounding responses in retrieved external knowledge mitigates factual "hallucinations"—confidently generated but unsupported content. Second, it lets a model answer questions about information it was never trained on, from current events to internal documentation. AWS notes that enterprises store vast amounts of information like manuals, FAQs, research reports, and customer service guides across various systems, and that context retrieval at scale is what determines generative output quality.
The RAG Data Flow: An Explanatory Model
The clearest way to understand RAG is as a pipeline in which data is transformed at each stage before reaching the model. The model below deconstructs the process into its four sequential stages, showing what happens at each step and why it matters for factual grounding. Practitioners describe the workflow as two phases: an offline ingestion phase that prepares documents, and a runtime phase that processes each user query.
| Stage | Function | Key Action | Benefit |
|---|---|---|---|
| 1. Indexing | Prepare external documents for search | Chunk documents and create embeddings stored in a vector database | Creates a searchable, current knowledge base |
| 2. Retrieval | Find information relevant to the query | Convert the query into an embedding and run semantic search against the index | Surfaces the right context at query time |
| 3. Augmentation | Integrate retrieved content with the query | Insert retrieved passages into a predefined prompt template | Gives the LLM explicit external context |
| 4. Generation | Produce the final answer | The LLM generates a response from the augmented prompt | Output is grounded in retrieved knowledge, mitigating hallucinations |
Reading the table as a chronology: documents flow downward through ingestion before any user query arrives, and each query then travels through retrieval, augmentation, and generation in turn. The mechanism by which RAG improves factual grounding is visible in the final handoff—the model is no longer answering from memory alone but from a prompt that contains the retrieved evidence.
Stage 1: Indexing External Knowledge
Indexing is the offline foundation of the pipeline. Document data is gathered alongside metadata and subjected to initial preprocessing—Databricks' reference architecture, for example, includes handling of personally identifiable information through detection, filtering, redaction, or substitution. The prepared documents are then chunked and embedded, with the resulting vectors held in a vector database where they must be indexed and regularly updated to maintain relevance and avoid stale or incomplete retrieval.
Chunking strategy is not a mechanical afterthought. Databricks emphasizes that preparing documents well, including chunking them based on the embedding model and the downstream application, is a key first step in a RAG reference architecture. Weaviate's technical introduction makes the same point from the production side: retrieval quality is heavily influenced by how content is chunked and indexed for search and filtering. Poorly sized or poorly structured chunks degrade everything downstream, because retrieval can only return what indexing made findable.
Stage 2: Query Processing and Retrieval
At runtime, a user's query is converted into an embedding so it can be compared against the indexed vectors. A similarity search then returns the top-k most relevant chunks from the knowledge base. This is semantic search in the service of generation: AWS distinguishes the two by noting that semantic search enhances RAG results for organizations adding vast external knowledge sources to their LLM applications, while RAG wraps retrieval inside a generative workflow.
The arXiv survey treats retrieval as a core component with its own optimization surface—indexing, query, and embedding optimization are all active areas of refinement. The practical implication for architects is that retrieval is a design decision, not a fixed utility. The same query can retrieve different results depending on how the index was built and how the query is represented, which is why retrieval quality is evaluated separately from generation quality.
Stage 3: Augmenting the LLM Prompt
Augmentation is the bridge between retrieval and generation. Once the most relevant data points from the external source have been retrieved, the augmentation process integrates this information by inserting it into a predefined prompt template, as Weaviate's Mary Newhauser explains. The original user question and the retrieved passages are combined into a single augmented prompt that carries the external context into the model.
Databricks describes the same step as feeding retrieved documents into the model as context, and Google Cloud's characterization of grounded generation—incorporating retrieved information seamlessly into the LLM to enhance its context—captures the intent. The template matters in practice: how retrieved chunks are ordered, labeled, and bounded within the prompt shapes what the model can reliably use, and the augmentation stage is where the pipeline's retrieval decisions become visible to the generator.
Stage 4: Generation of Grounded Responses
In the generation phase, the augmented prompt is injected into the model's context window and the model produces the final response. The model combines its internal language understanding with the augmented external data to produce a coherent, contextually appropriate answer, rather than reciting retrieved text verbatim. Google Cloud describes the outcome as more precise and informative responses enabled by the augmented context.
This is where the architecture's core promise is realized. Because the response is generated against retrieved, current, domain-specific evidence rather than static training data alone, the output is grounded in the provided external context—which is the mechanism by which RAG mitigates hallucinations. It is worth noting the boundary: grounding depends on the quality of what was retrieved, so generation inherits both the strengths and the failures of the earlier stages.
Evaluating RAG System Effectiveness
RAG systems are evaluated using a combination of relevance scoring, groundedness checks, human evaluations, and task-specific performance metrics. Databricks is explicit about why: because RAG combines retrieval and generation, traditional AI evaluation methods alone fall short of capturing both the quality of the retrieved context and the accuracy of the final response. A fluent answer built on irrelevant retrieved documents, or a relevant retrieval the model ignored, both look fine to a conventional benchmark.
Two families of metrics cover the two halves of the pipeline. Retrieval quality is assessed with context-oriented measures—Context Precision and Context Recall evaluate how well relevant documents were fetched. Response quality is assessed with groundedness measures—Faithfulness and Answer Relevance determine whether the model's output is actually supported by the retrieved context. Databricks also notes that evaluating output accuracy ultimately requires a combination of human judgment, relevance scoring, and groundedness checks, so automated metrics supplement rather than replace review.
Implementing and Evaluating RAG for Enhanced LLM Applications
Developers and architects should implement RAG to enhance LLM factual accuracy and relevance, particularly for knowledge-intensive or domain-specific applications, by carefully designing and evaluating each stage of the pipeline. The four-stage model gives a diagnostic structure: hallucinated or vague answers can originate in any stage, and the metrics localize the fault—low Context Recall points to indexing and retrieval, while low Faithfulness points to generation ignoring its context.
The measurable indicator of success is improved scores on RAG evaluation metrics such as Answer Relevance, Context Precision, and Faithfulness in production environments. Because Databricks notes that indexed data must be regularly updated to avoid stale or incomplete retrieval, these scores should be treated as ongoing signals rather than one-time validation, with re-measurement after each significant change to the knowledge base, chunking strategy, or prompt template.
Sources
- What is Retrieval Augmented Generation (RAG)? — Databricks
- What is RAG (Retrieval Augmented Generation)? — IBM
- Retrieval-Augmented Generation for Large Language Models: A Survey — arXiv.org
- What is RAG? - Retrieval-Augmented Generation AI Explained - AWS — Amazon Web Services, Inc.
- Introduction to LLM RAG - Retrieval Augmented Generation Explained — Weaviate
- What is Retrieval-Augmented Generation (RAG)? — Google Cloud